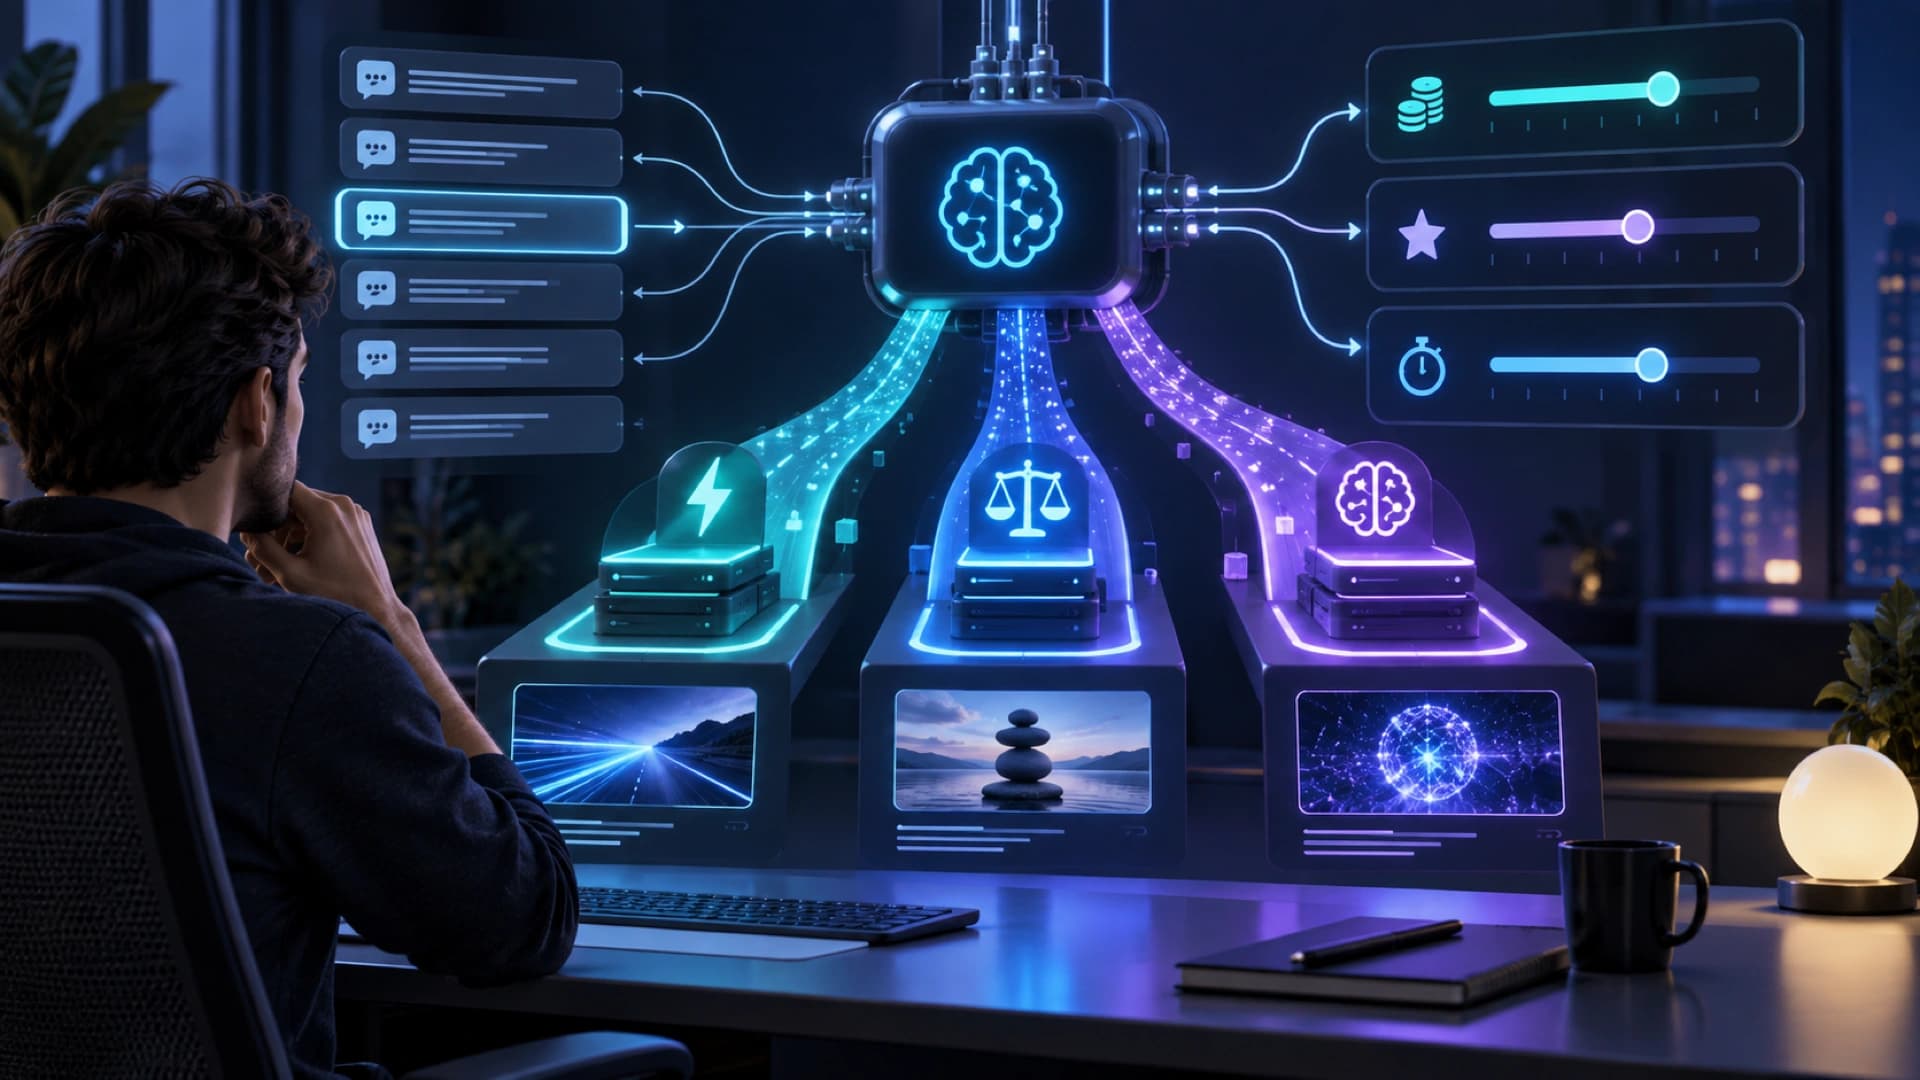
GitHub announced on August 7, 2026 that Lite and Balanced effort levels for Copilot code review are generally available. The feature is not simply another model label. It lets teams choose how much review effort to spend based on the complexity and risk of a pull request.
GitHub positions Lite for straightforward changes, documentation updates, and small fixes. Balanced is intended for larger, more complex, security-sensitive, or cross-service changes where deeper analysis from a higher-reasoning model is useful. The result is a code-review workflow with adjustable depth instead of one fixed level of scrutiny.
Organization administrators can set an organization-wide default that repositories inherit, while individual reviews can still choose a different effort level. A team can therefore establish a common baseline without forcing every documentation change through the same heavier analysis path.
The GA release also renames the preview levels. Low and Medium are now Lite and Balanced, and existing configurations carry forward under the new names. GitHub says the timeline events and pull request overview comment identify which effort level was used, making review depth visible after the run.
The feature is available on Copilot Pro, Pro+, Max, Business, and Enterprise plans. That makes it a formal product capability, but access still depends on the team’s plan, organization settings, and repository policies. General availability does not mean every GitHub account automatically receives the same permissions.
For engineering teams, the practical value is aligning review budget with risk budget. Low-risk changes do not need to consume the deepest reasoning path every time, while sensitive or cross-service changes can explicitly request Balanced. Effort level only changes the depth of AI review; it does not replace human judgment about requirements, architecture, security, or business impact.
Lite and Balanced also show how agentic development tools are gaining operational controls. The next question is not only whether a model can read code. It is whether a team can make the same AI tool participate in software delivery with different modes for risk, cost, latency, and approval workflow.