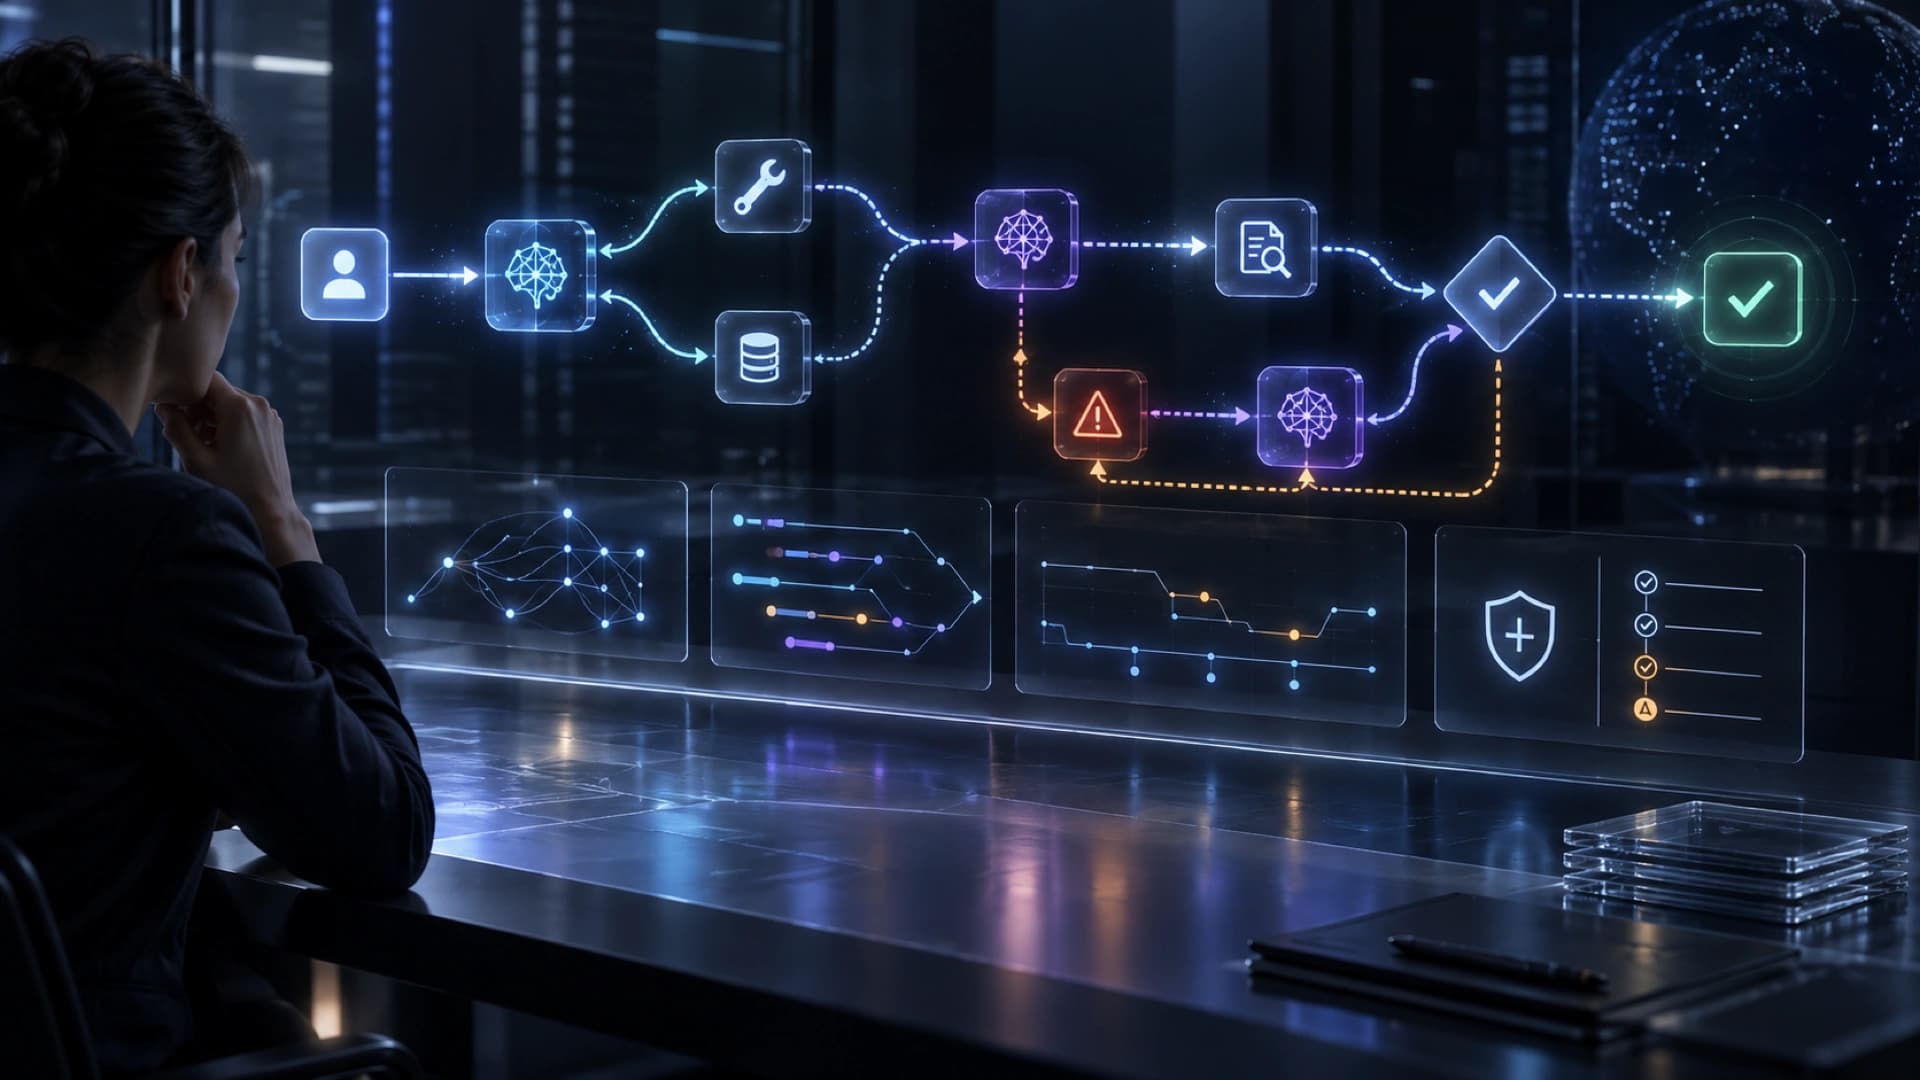
NVIDIA introduced NeMo Relay on September 30, 2026 as a common observability layer for AI agents. It captures ordered lifecycle events and structured trajectories so developers can inspect not only whether an agent finished, but also how many model calls, tool actions, retries, errors, seconds, and tokens the run consumed.
The article demonstrates the system with Hermes Agent. With native NeMo Relay integration, Hermes can produce ATOF event streams, step-by-step ATIF trajectories, and OpenTelemetry spans labeled with OpenInference, which can be inspected in tools such as Arize Phoenix. ATOF reconstructs individual execution events, timing, and parent-child relationships. ATIF presents the path step by step. OpenTelemetry helps inspect model and tool spans, latency, token use, and errors.
That separation matters because a model's tool request does not prove that the tool succeeded. NVIDIA says outcome verification requires matching tool start, tool end, and error events through their shared UUID and checking the parent relationship. Saving only the agent's final answer hides failed searches, repeated file reads, and recovery behavior, making it difficult to tell what a harness change actually improved.
NVIDIA shares a Hermes ToolPerf case study comparing a pinned baseline and fixes across 108 runs on two models. In one Qwen Coder 30B example, task success rose from 19/27 to 22/27, while mean LLM calls rose from 3.8 to 4.9, tool calls from 2.8 to 3.9, tool-result data from 16 KB to 33 KB, and mean duration from 27 seconds to 42 seconds. The result shows why a higher success rate can come with more recovery work; a single success number is not the whole efficiency story.
NeMo Relay also creates a data-governance concern. Depending on configuration, traces can contain prompts, model responses, tool arguments and results, file paths, and other application data. Those records need review and appropriate redaction before being sent to Phoenix or another OTLP backend. Observability can be an evidence layer for governance, but it can also become a new sensitive-data surface rather than an automatically harmless debug log.
A stronger evaluation workflow pairs a deterministic verifier with traces. First use a fixed task and exact success check to establish what happened. Then use the trajectory to explain changes in model calls, tool retries, errors, and cost. That is more reliable than treating fewer tool calls as an automatic improvement, and it helps teams see when a fix works only for a particular model, task, or environment.