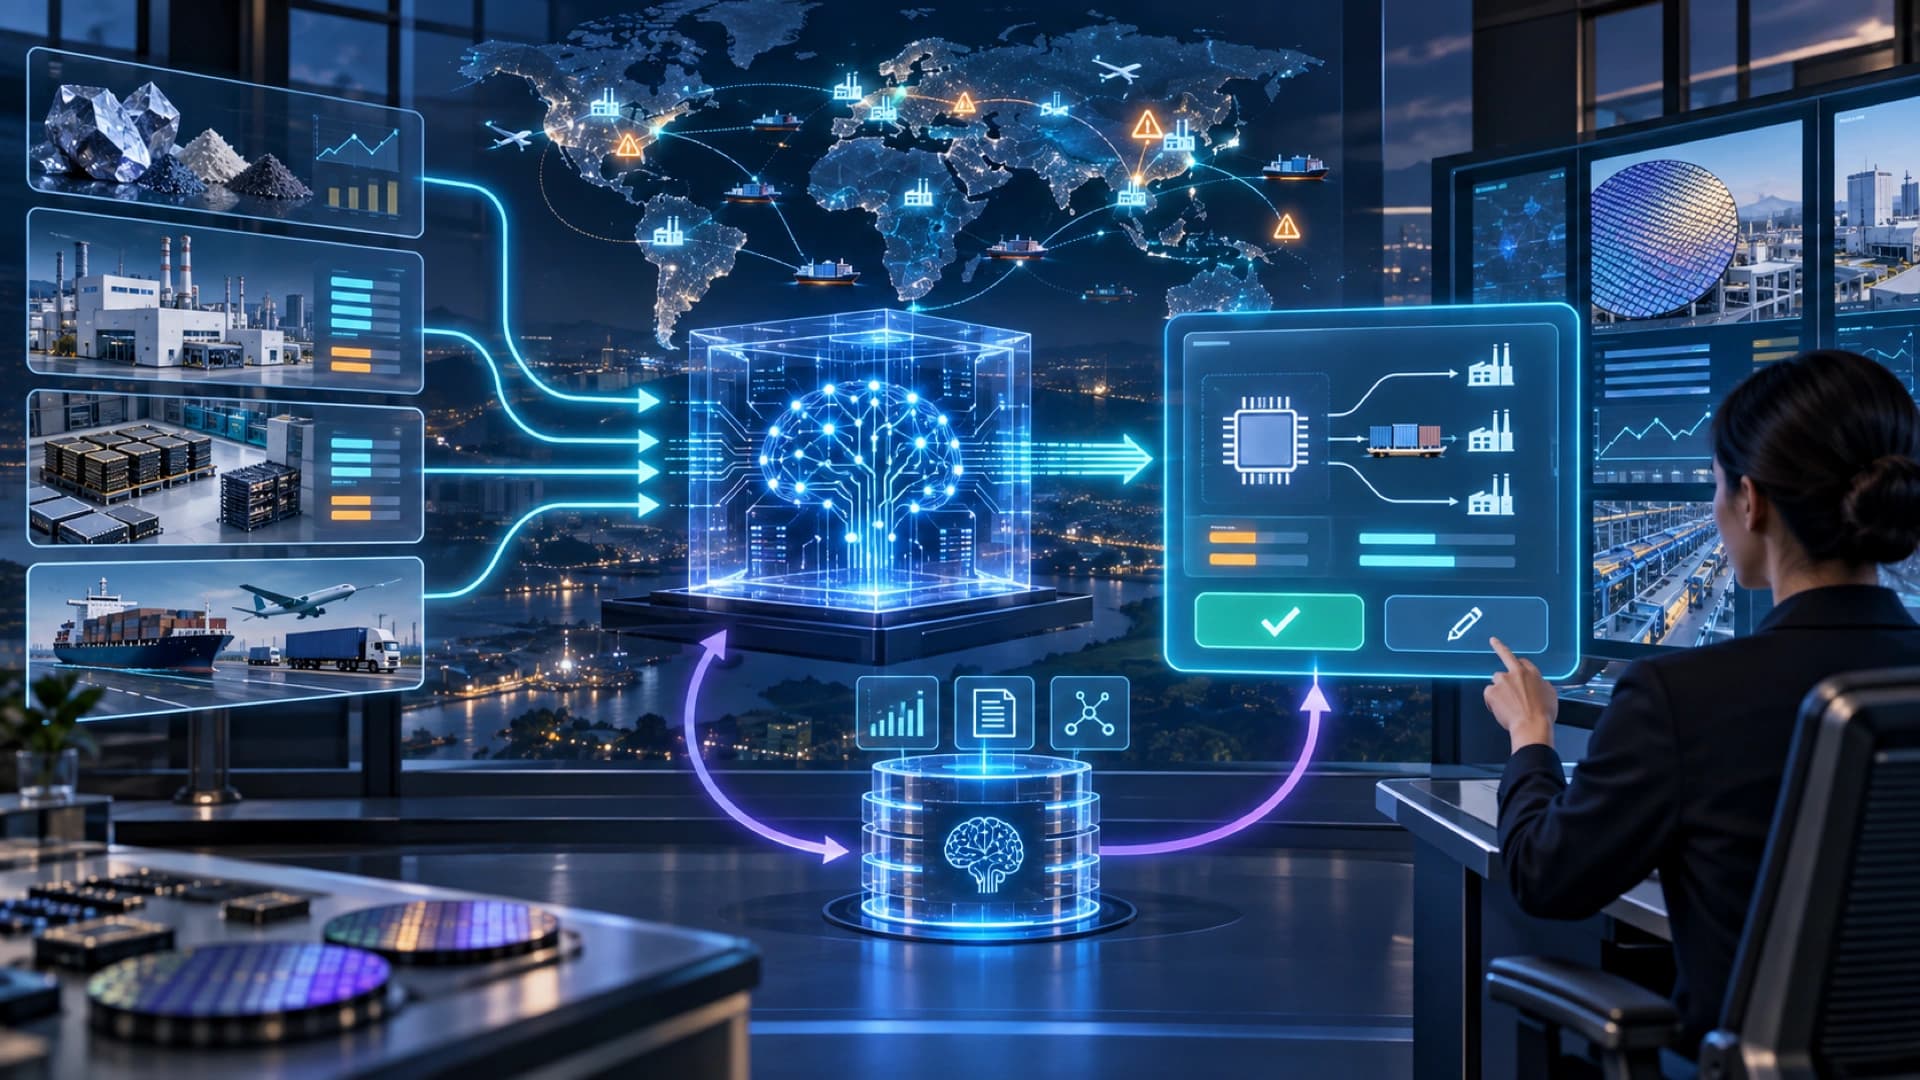
NVIDIA shared a Digital Supply Chain Intelligence command center built with Palantir on September 10, 2026. It addresses the time from wafer-out to first token: GPUs, CPUs, memory, manufacturing sites, commitments, and transport conditions change every week, forcing a new decision about where constrained material should go. The important design choice is not replacing planners with AI. It is bringing quantitative and qualitative signals into one decision workflow.
Palantir Foundry’s Ontology connects materials, manufacturing sites, commitments, capacity, allocations, production outputs, and unstructured signals into a governed operational layer. NVIDIA’s command center surfaces risks, blockers, a decision queue, supply movements, and capacity trends so planners can simulate scenarios. The data model matters more than simply sending more tables to a model because it preserves relationships between objects and the context that was knowable when each decision was made.
NVIDIA cuOpt handles the quantitative side. It formulates material allocation as a mixed-integer linear program that minimizes Time of Ownership, or TOO, and reports the binding constraints that actually limited the result that week. Planners get more than one allocation: they can explore what would happen with less memory or a new manufacturing site. The solver owns the defined mathematical space, leaving people to focus on tradeoffs and exceptions instead of manually recomputing every combination.
Historical backtesting by NVIDIA and Palantir also showed what the mathematical model could not see. Planners used emails with partners, weather forecasts for important regions, geopolitical events, supplier debriefs, and years of experience. Those signals could change an allocation that looked reasonable in the structured data. The workflow therefore writes the decision, rationale, expected result, and actual outcome back into the Ontology, turning expert judgment into inspectable and replayable data.
The next step is a specialized model. NVIDIA says it selected Nemotron 3.5 Lightning as the execution layer in an agentic workflow. The model has about 30 billion parameters and roughly 3 billion active parameters per forward pass. The data process includes NeMo Anonymizer, NeMo Data Designer, LoRA supervised fine-tuning, and a point-in-time backtest. Palantir Autopilot manages training, deployment, monitoring, and lineage. The deployed model returns a recommendation, rationale, and attached risks; a planner makes the final call.
On the development benchmark reported by NVIDIA, post-trained Nemotron 3.5 Lightning reached 86.7% allocation-decision accuracy, compared with 55.5% for Nemotron 3 Ultra and 17.5% for the base Lightning model. Balanced accuracy and Macro-F1 were 58.6% and 57.5%. These numbers come from NVIDIA and Palantir’s specific workflow, data, and evaluation design, not a general benchmark across supply chains or enterprises. The more transferable idea is using point-in-time replay as a gate before deployment.
The feedback loop has an explicit limit. Accepted, edited, overridden, and production outcomes are written back into the Ontology, and another governed training run is considered only after enough representative data accumulates. NVIDIA says the model does not retrain itself in production. In the future, accepted and overridden recommendations may become preference pairs covering decision correctness, policy compliance, and evidence grounding. That preserves a review point before model changes and prevents one bad recommendation from silently rewriting the next policy.
The case points to a practical enterprise pattern: combine expert judgment, data relationships, an optimizer, a specialized model, and human approval in one decision loop. The model is neither an isolated predictor nor an unsupervised buyer. It makes a recommendation in replayable context and feeds the result into the next evaluation cycle. For any workflow with exceptions and tacit knowledge, recording what was knowable, what was done, why, and what happened can create more durable value than starting with a larger model.