OpenAI launched GPT-Live-1 in the API on September 10, 2026, bringing ChatGPT-style full-duplex voice conversations to developers. The model can listen and speak at the same time, handle interruptions, pauses, background noise, and backchannels, and let developers shape tone, pace, and conversational style. This is an architecture change for voice agents, not only a voice-quality update.
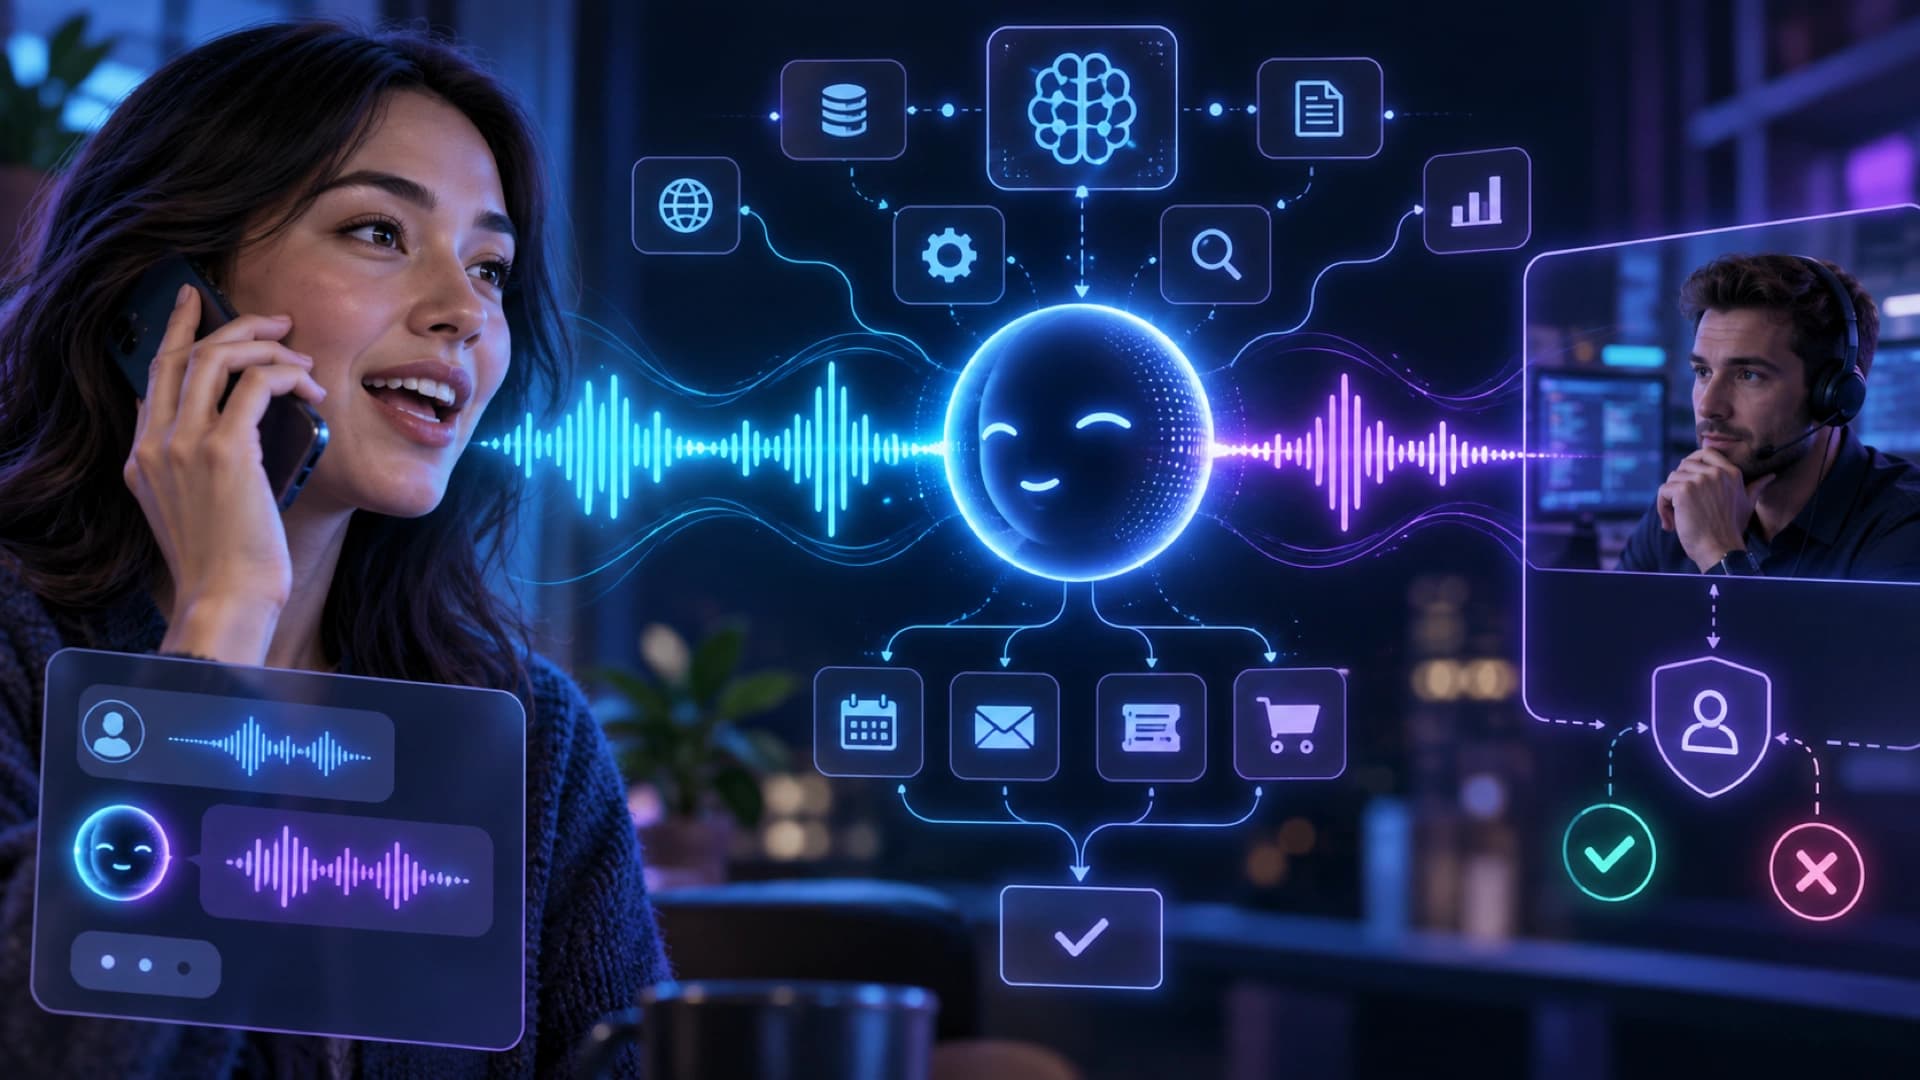
Traditional voice agents often chain speech-to-text, a reasoning model, and text-to-speech. Every handoff can add latency or lose context. GPT-Live-1 keeps listening and speaking in one voice layer, then delegates deeper reasoning and actions to a backend text model, tools, or agent framework. Application teams can adjust the conversation layer and business execution layer separately.
OpenAI lists interruption handling, background-noise and silence management, long-session reliability, ASR transcripts, response text, keyword biasing, turn detection, and telephony support. That can make a voice interaction feel more like a natural call. Reservations, order changes, account questions, and support actions still need to be executed by backend systems under explicit permissions.
GPT-Live-1 can delegate reasoning and tool calls to GPT-6 Astra or a third-party model. A faster backend can handle scheduling and order updates, while a deeper reasoning model handles complex customer issues. This separation can balance latency, cost, and task difficulty, but it also requires clear delegation, timeout, error-recovery, and human-escalation behavior.
OpenAI says an early Speak evaluation cut interruptions by almost 80% compared with its previous turn-based system. OpenAI also reports a 30-point improvement over GPT-Realtime-2.1 on its Full Duplex Bench and a number-one Tau3 result when paired with GPT-6 Astra at medium effort. These are vendor or customer early results: directional product evidence, not independent benchmarks that automatically generalize to every voice workflow.
The front-end voice layer is priced at $0.05 per minute, with backend model and tool usage billed separately. Teams therefore cannot judge total cost from the voice rate alone. They also need to account for reasoning, search, databases, telephony, recording retention, human transfers, and failed retries. Lower interaction latency does not necessarily mean lower total operating cost.
OpenAI also describes Presence as a way to build enterprise voice workflows on top of GPT-Live-1, where agents answer questions, resolve issues, use company systems, take approved actions, and escalate to people. That makes the boundary clear: the voice layer is not the complete security boundary. Identity, sensitive data, payments, account changes, approval, and audit design remain application responsibilities.
GPT-Live-1 shortens the path between natural conversation and agent execution. It could improve phone support, reservations, language learning, and field assistance, but deployment quality will still depend on backend tool permissions, data sources, human escalation, recording privacy, and a clear definition of task success. Natural speech is the entry point; workflow governance determines the outcome.