An August 7, 2026 arXiv paper, marked as accepted by ASE 2026, introduces AgentChaos and applies chaos-engineering fault injection to agent systems. The focus is not which LLM produces the best answer. It is whether a workflow can sense and handle controlled failures introduced into different parts of the runtime.
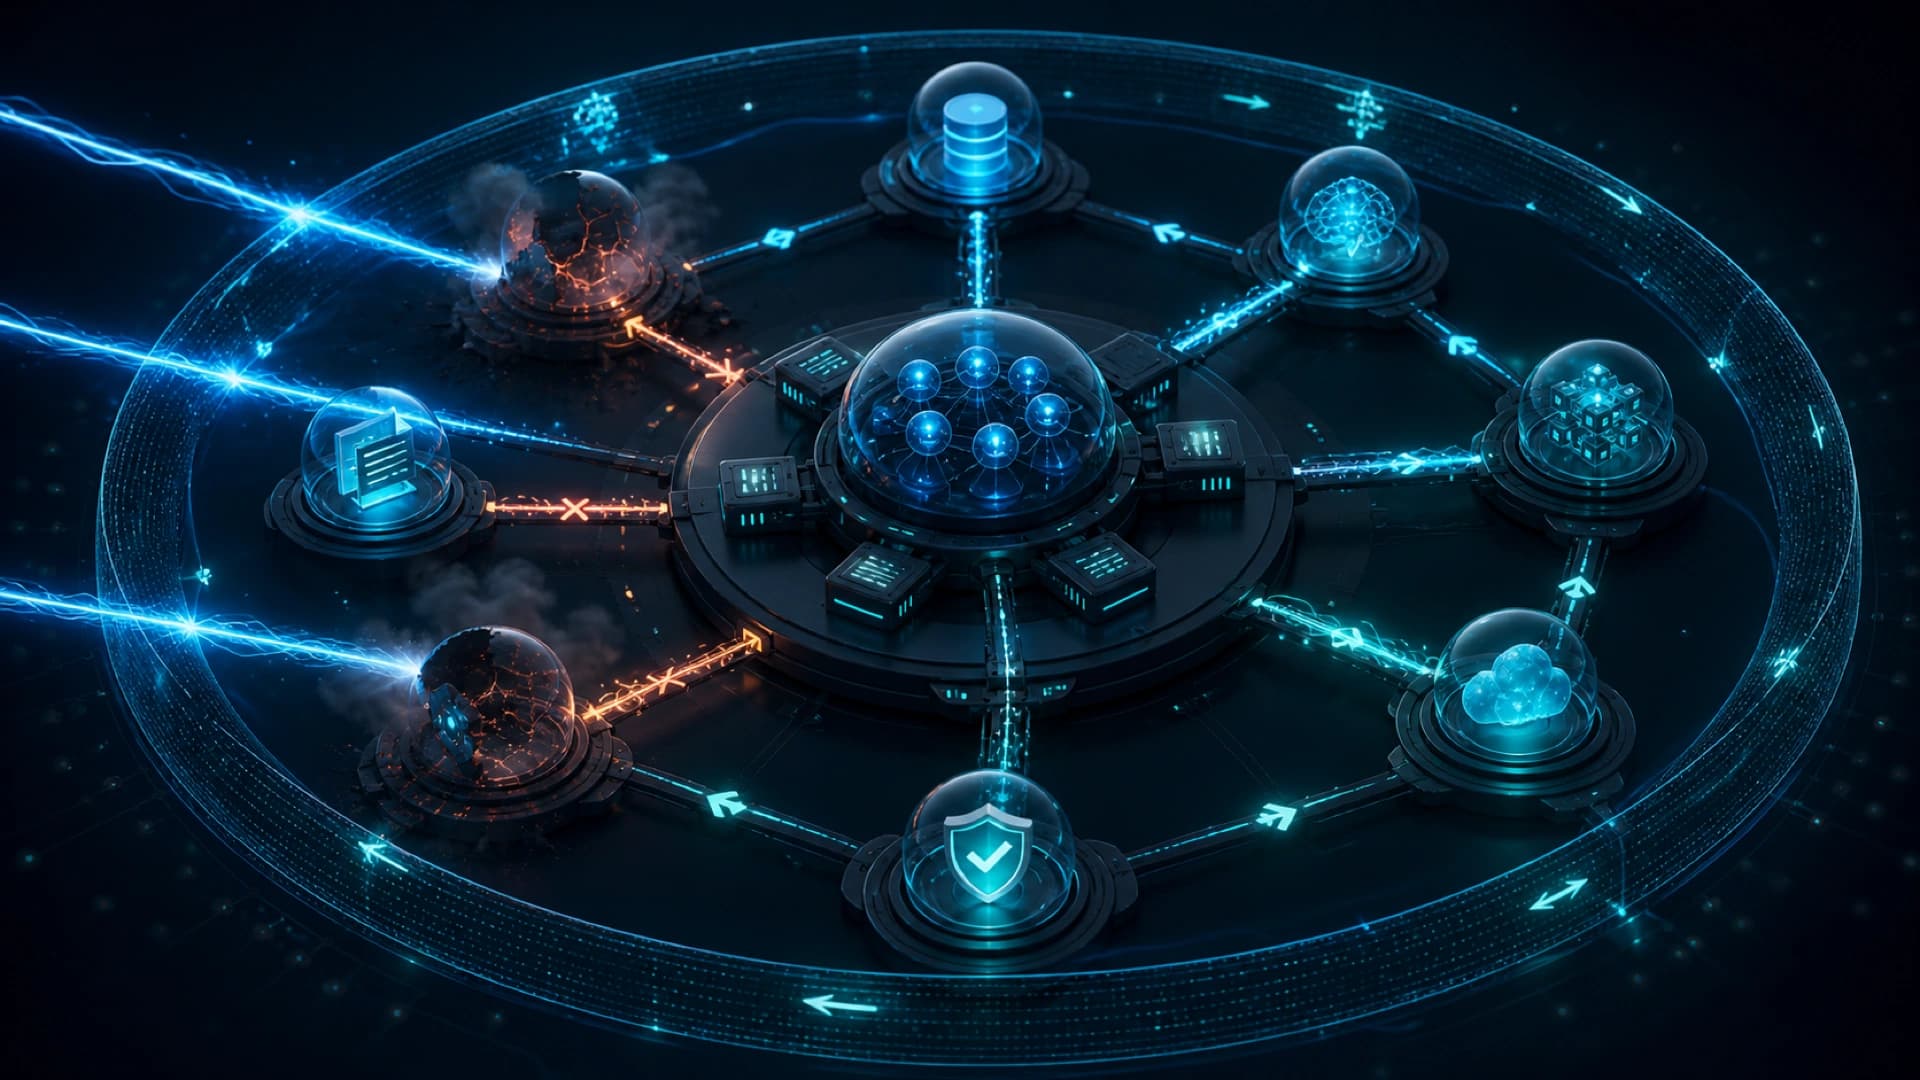
AgentChaos performs non-intrusive fault injection at a shared HTTP layer, so it does not require rewriting each agent framework. The paper describes crash, omission, and value faults targeting message content and tool-call fields. It also verifies that an injected fault was actually triggered, avoiding a test that appears to run without changing the system under test.
This resembles real production-agent failure modes. An agent may receive a syntactically valid but incorrect tool response, lose a required event, crash midway, or pass an unsafe parameter to a downstream service. Testing only pass@1 under normal inputs says little about whether the orchestrator, retries, timeouts, state recovery, and human escalation paths work.
Across 65 configurations, the paper reports that fault injection reduced pass@1 by as much as 50 percentage points in some systems. The authors also report broadly consistent rankings across models, suggesting that agent robustness may depend more on system implementation than on the underlying model alone. These are research results for the paper’s benchmarks and configurations, not a production failure rate for every agent.
The engineering lesson is to evaluate model mistakes separately from the system’s ability to handle errors. A test plan can put tool errors, empty responses, delays, duplicate events, malformed values, and authorization denials into a fault matrix. Each row should have an explicit timeout, retry cap, idempotency behavior, alert, and human-takeover expectation.
Fault injection needs its own safety boundary. Test traffic should run in an isolated environment, every injection should have a trace ID and replayable record, and destructive faults should not reach real production data. Systems with tenants or sensitive information also need least privilege and redaction around the fault harness itself.
The approach is especially relevant when an agent can edit code, send messages, or call external transaction services. The goal is not that no fault ever causes a task to fail. It is that the system stops in an acceptable state, explains the failure, and does not repeat an irreversible side effect.
AgentChaos moves agent testing from static benchmarks toward runtime resilience. As agents connect to more tools and longer workflows, the ability to observe, diagnose, and recover under controlled faults will shape usability as much as the model’s reasoning ability.