On October 1, 2026, Anthropic published a guest post by physicist Matthew Schwartz introducing the idea of “Claude-shaped problems.” Instead of asking a model to imitate every part of a human scientist’s job, the approach looks for problems that current large language models are unusually good at and that can be checked. Schwartz built BootLoops around that idea: an open-source toolkit and set of protocols for exact calculations in quantitative science.
The post starts with a practical limitation. Claude and GPT can process broad knowledge, code, mathematics, statistics, papers, and data, but that does not make them human scientists with reliable conceptual judgment. Schwartz calls the gap an impedance mismatch. BootLoops places the model inside a more suitable harness where it can reuse tools, run calculations, and produce checkable results, while human researchers decide whether the question has scientific value.
The first projects focused on scattering amplitudes and the semi-numerical bootstrap. Schwartz says Claude consolidated code and methods from different papers into a common framework and completed 30 integrals end to end: 15 reproductions of known results and 15 that had not previously been computed. Those figures are part of the article’s research account. They demonstrate the potential output of the tool-and-agent setup, not independent confirmation of every new result.
BootLoops was then applied to ecology, population genetics, economics, and linguistics. The post describes technically plausible connections involving forest neutral theory, genetic variation, replication packages, and word-stress data. But technical correctness was not the same as scientific importance. Schwartz brought in experts from each field to turn what the model found into questions that researchers actually care about. Some initial results were judged uninteresting; others became meaningful after collaboration and redirection.
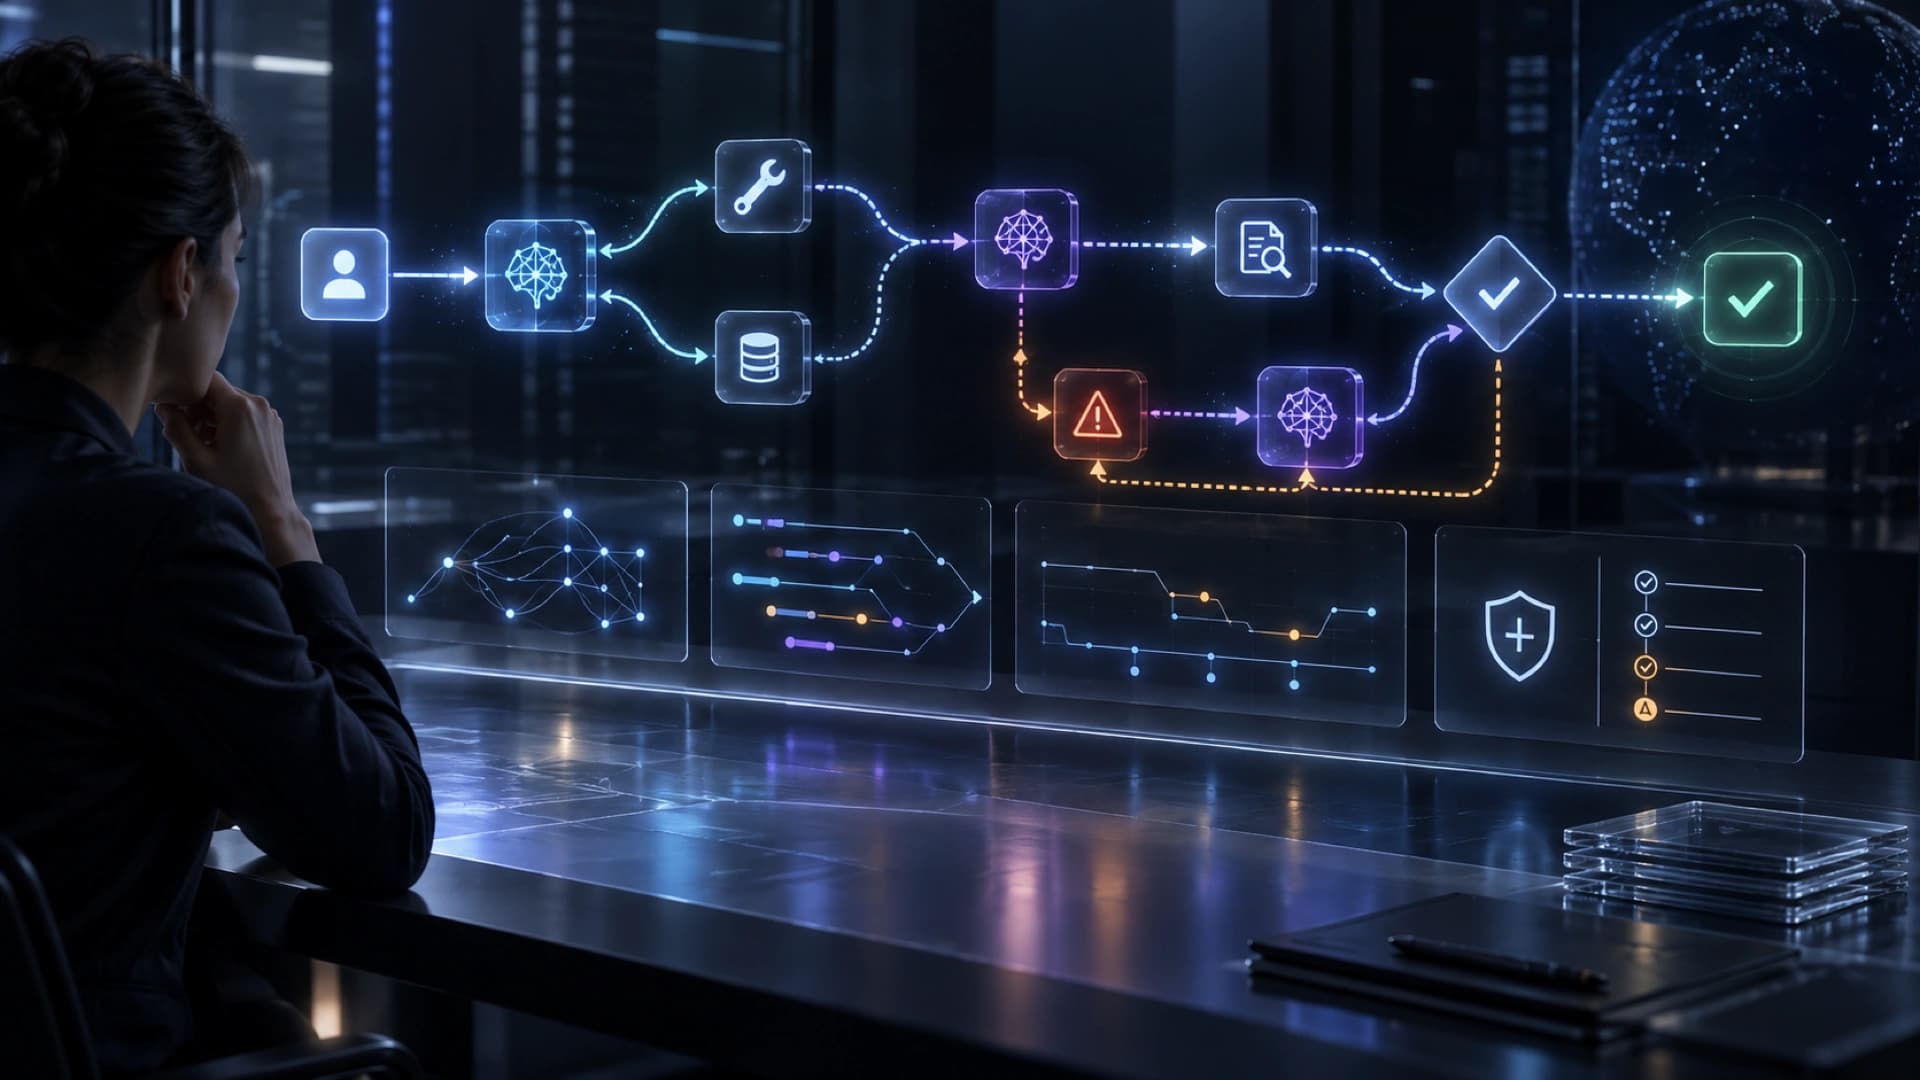
The workflow requires substantial orchestration. Schwartz describes multiple Claude Code sessions running on Google Cloud VMs for computation, writing, tool creation, and adversarial review, coordinated by a master session that manages resources and validates results. Intermediate work is stored in Markdown files. Even with the harness, the model can declare victory too early, misjudge time, grind through inefficient paths, or lose context on long tasks. Researchers still need rigid success criteria, visual inspection, and persistent questioning of conclusions.
The post also discloses that BootLoops is not an Anthropic project; it is owned and maintained by Schwartz, who was a visiting researcher at Anthropic during the work. The careful takeaway is that this is an early scientist-led case study. AI’s near-term value may be strongest in a verifiable loop of tools, computation, cross-field search, and expert judgment—not in a single prompt that replaces the scientific method.