GenRouter, an arXiv preprint submitted on August 17, 2026, addresses a practical AI workflow problem: an image agent should not run the heaviest pipeline for every prompt. Existing systems often build search, reasoning, verification, or iterative-generation workflows in isolation. The result is fragmented capability, while simple requests are forced to pay for complex computation.
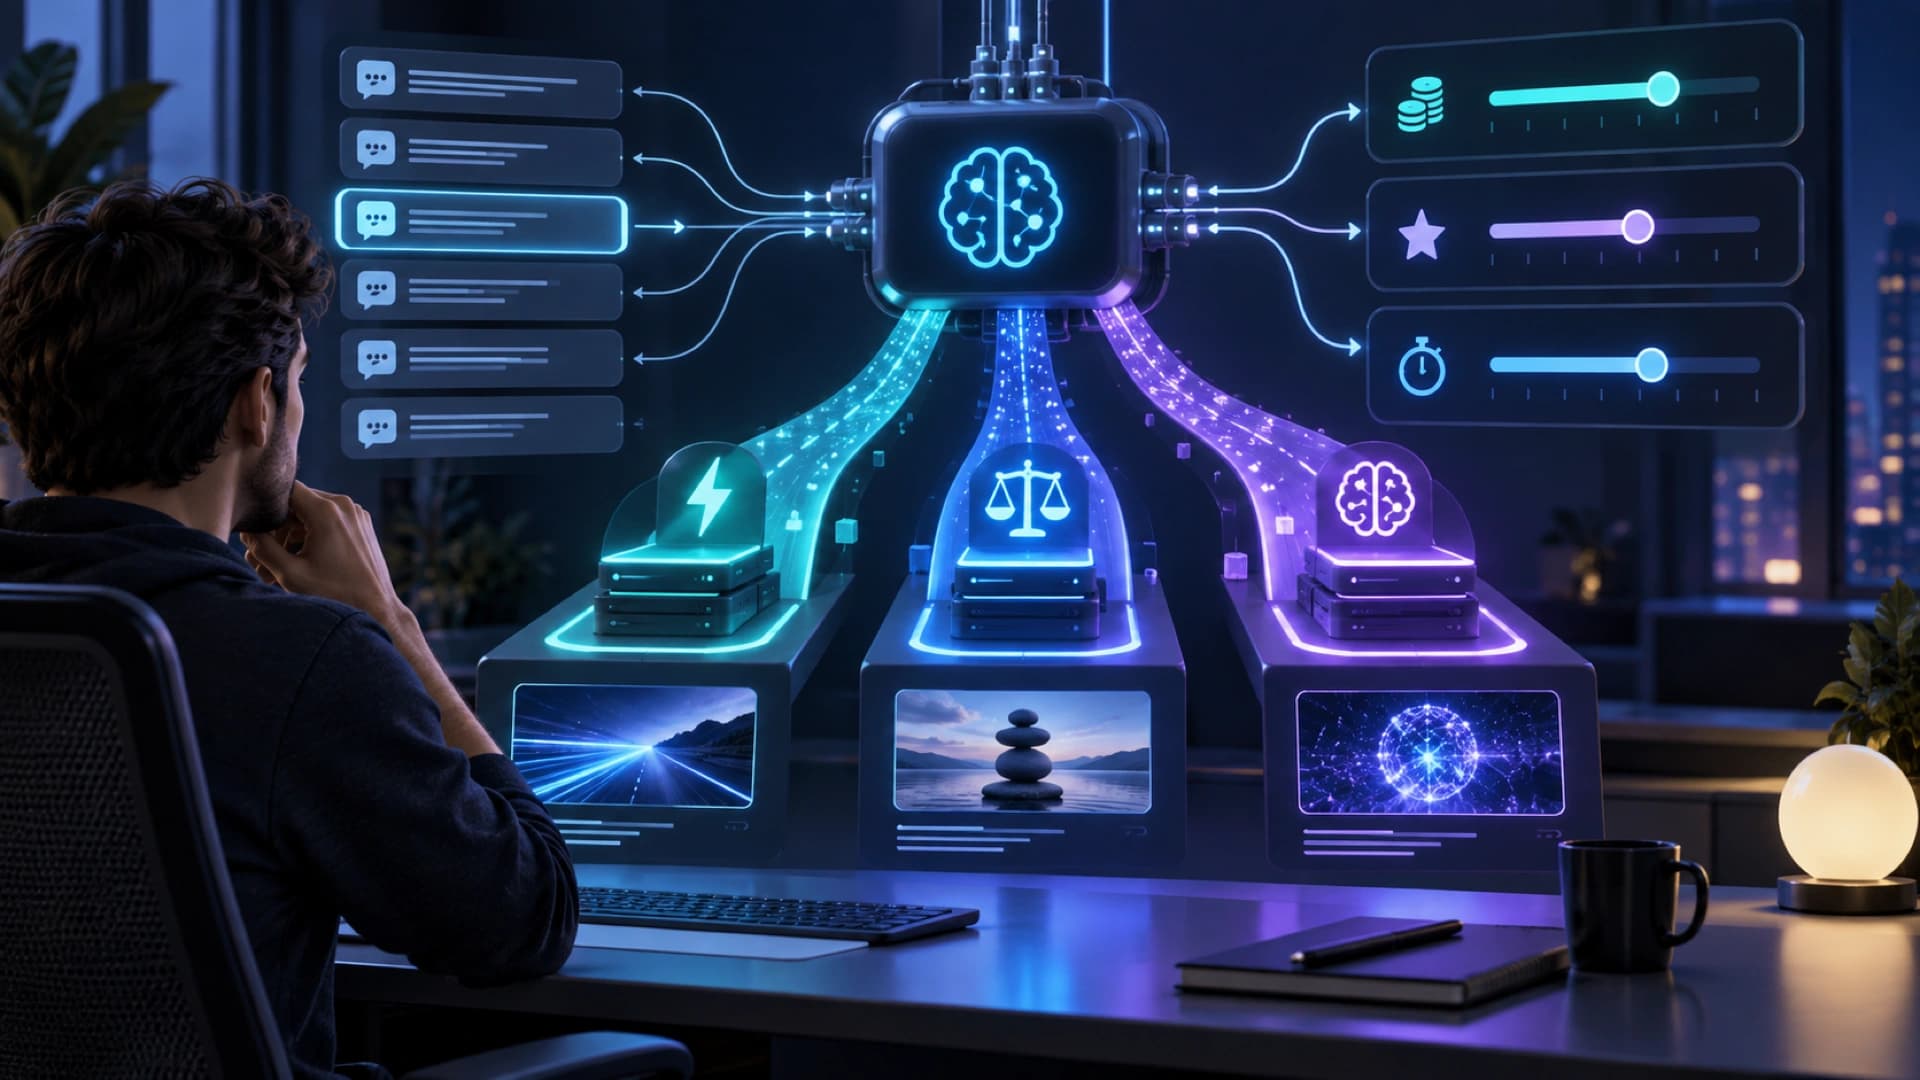
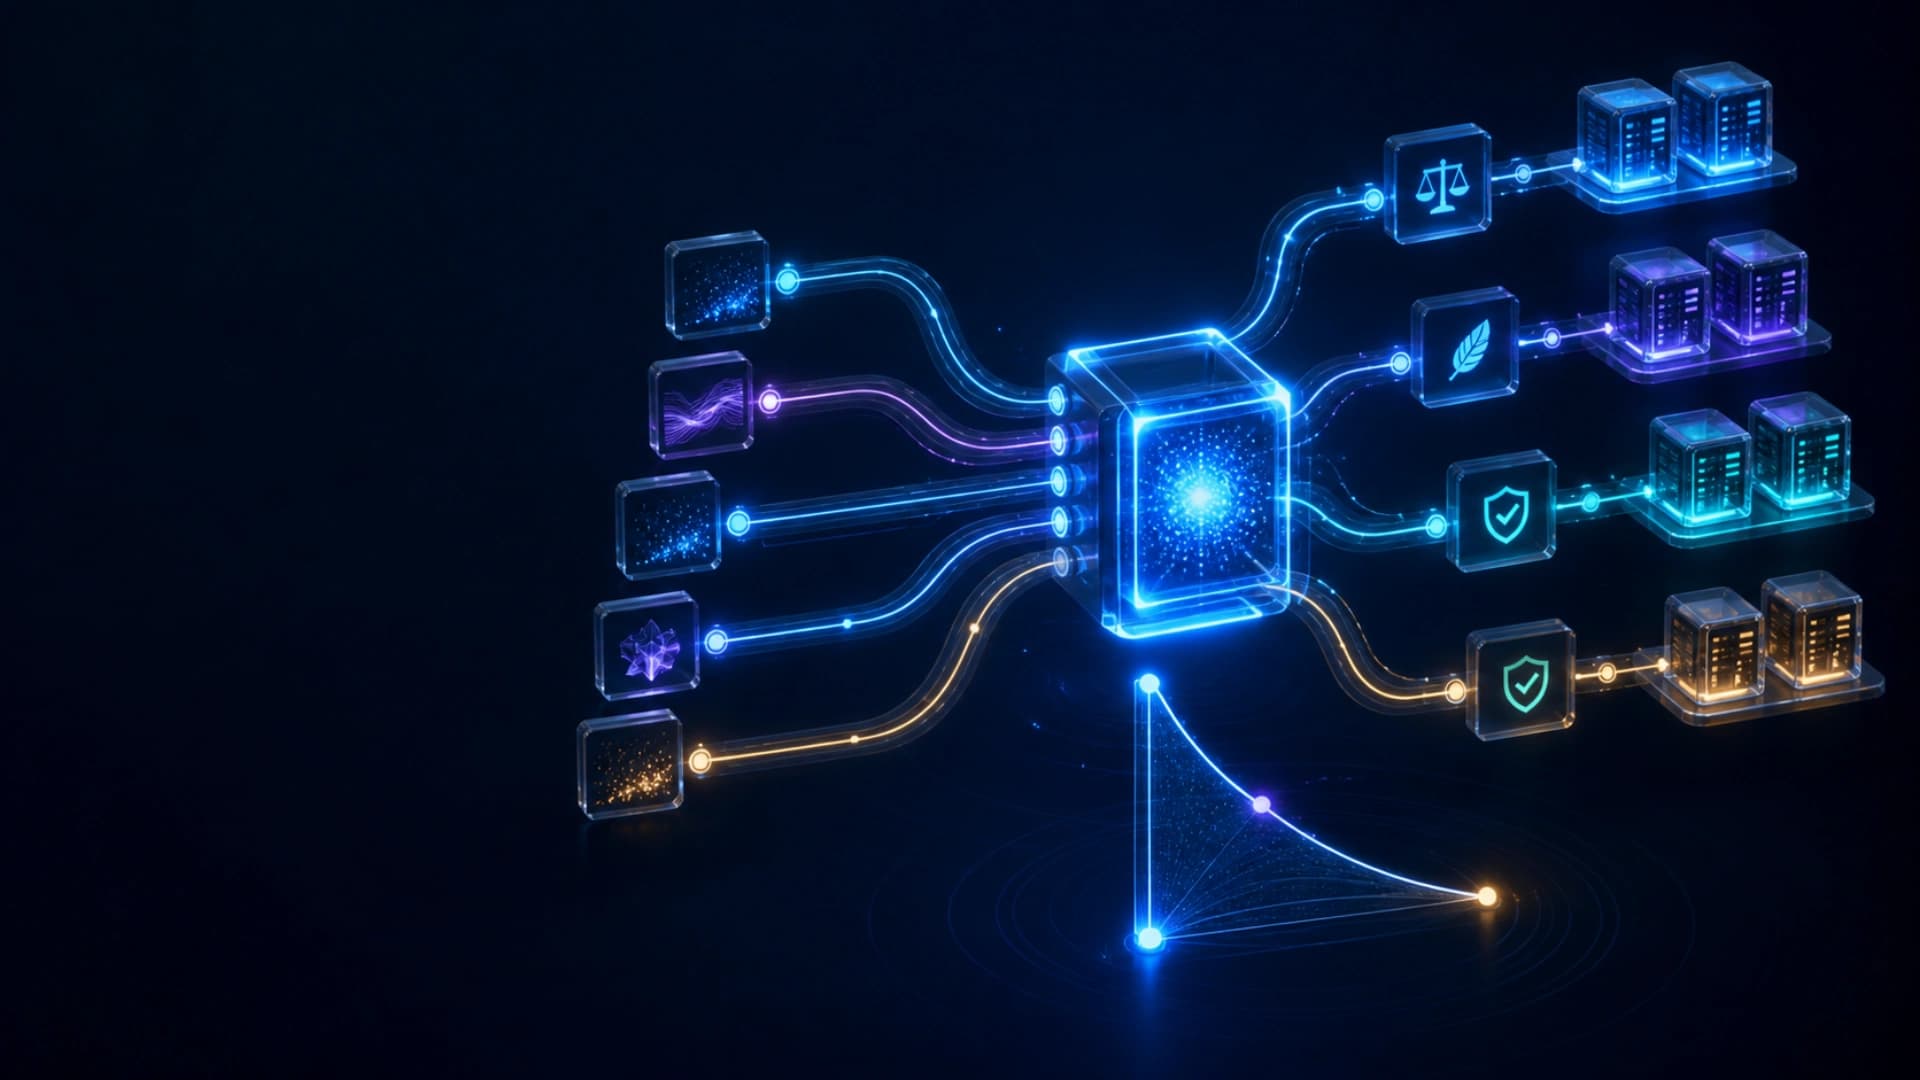
The authors propose GenCanvas, which standardizes different agentic image pipelines into foundational primitives and executable templates. GenRouter then uses demand profiling, experience matching, and Pareto filtering to select a workflow that balances visual quality, cost, and latency. The design separates what the model generates from which steps the system should run first, making the router itself an evaluable decision layer.
Across five benchmarks, the authors report an average overall score of 71.3% for GenRouter with GenCanvas. Against the heavier GEMS pipeline, they report execution cost falling from $59.70 to $2.97 and latency from 13.62 hours to 4.68 hours. These are results from the paper's experiments. Benchmarks, models, API prices, and execution environments affect the numbers, so they are not a universal cost guarantee for image services.
The point of routing is not only lower price. The paper shows that aesthetics-focused prompts more often use lightweight text-enhancement workflows, while prompts with complex spatial or logical constraints trigger reasoning, hybrid, or verification templates. For workflow design, the division is important: expensive checks and iterative repair should be activated by demand instead of applied by default.
The study also tests accumulated experience. After adding routing experience from three benchmarks, performance on a mixed test set rises from 73.5 to 75.2 while cost and latency fall by 8.7% and 7.9%. In a zero-shot transfer test, the authors report that frozen experience outperforms a standard LLM-as-router while using less cost. These are preprint findings that need reproduction across different models and prompt distributions.
For a real content workflow, the lesson is to classify requests as simple, constrained, or high-risk, then define minimum steps, optional verifiers, cost limits, and human review for each class. The routing decision should also retain its reason, selected template, retries, and quality outcome. Otherwise, token savings can be erased by opaque failures and manual rework.
GenRouter shifts the agentic image-generation question from how strong one model is to how a system allocates computation by need. For AI marketing, design, and content teams, a reliable workflow does not mean maximum reasoning on every request. Complexity, verification, and cost should follow task risk, with held-out prompts checking that the router has not simply memorized one benchmark.