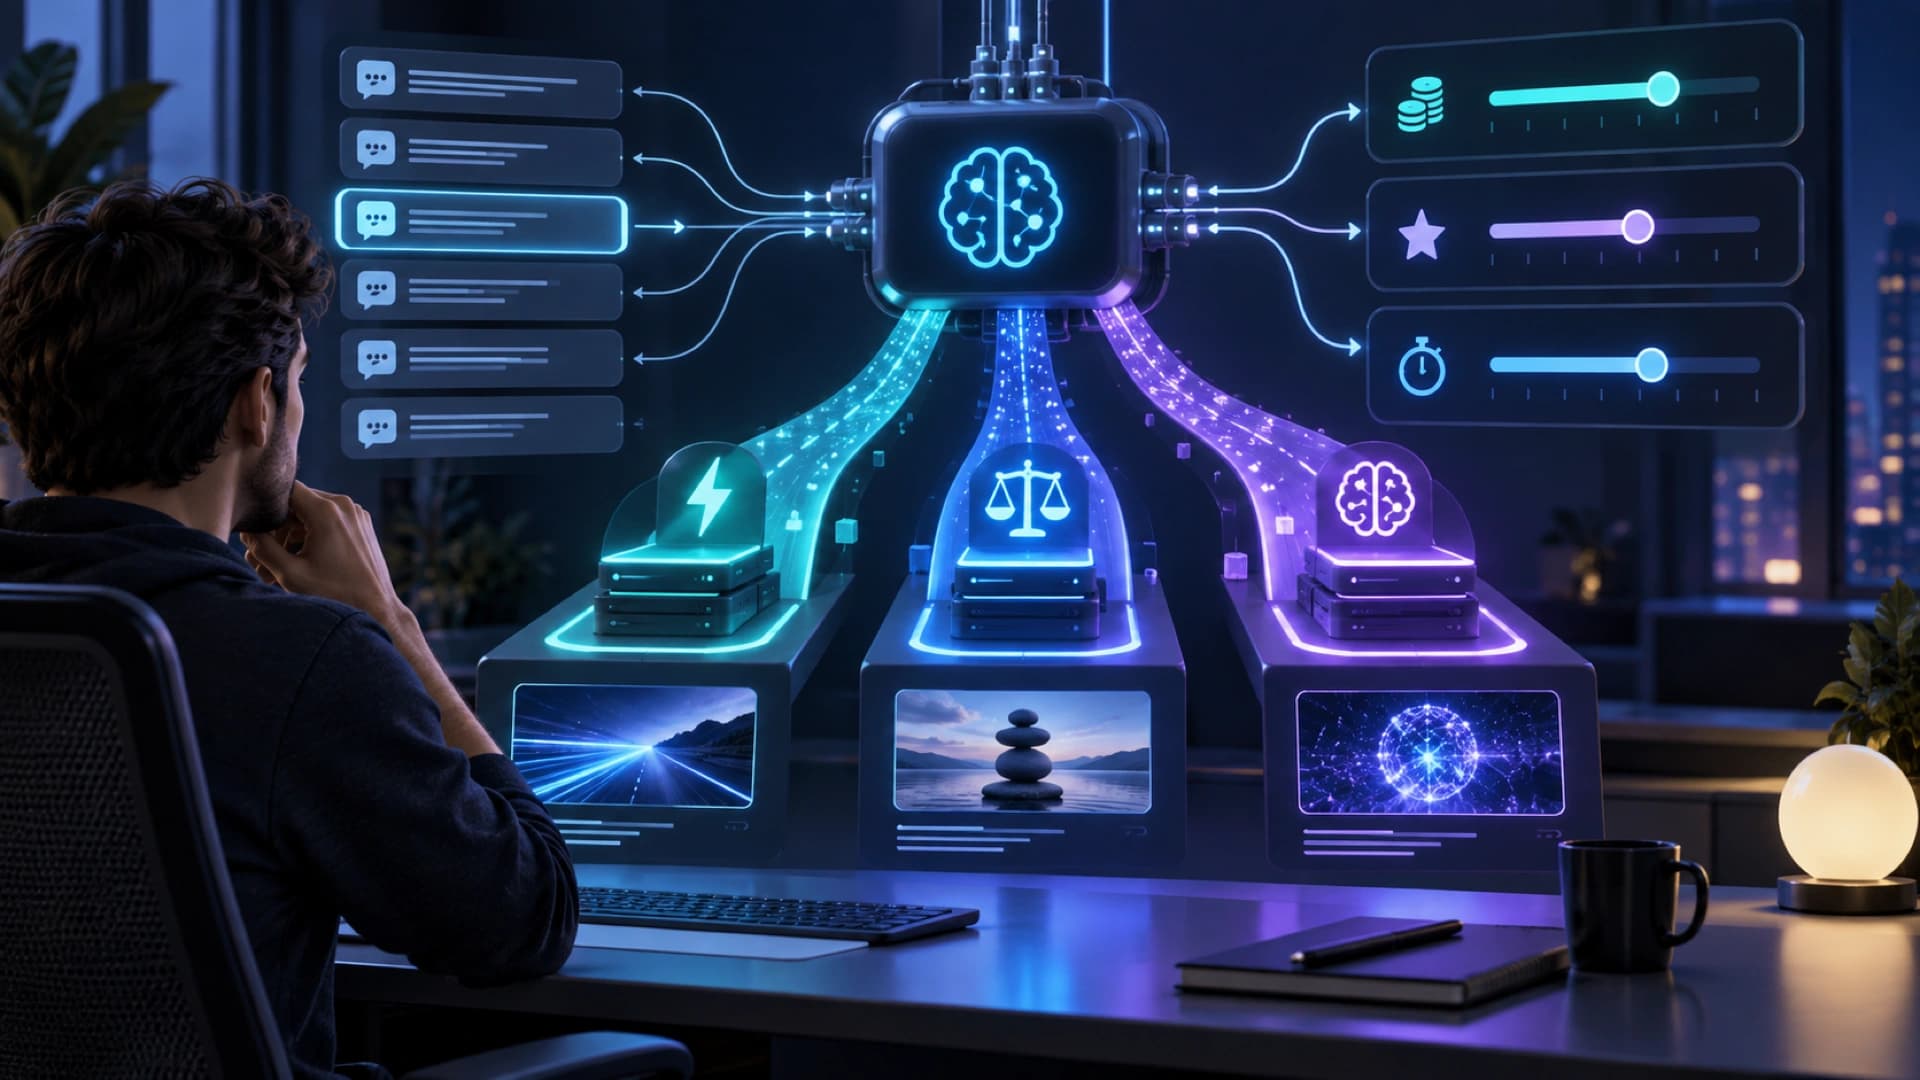
GitHub updated Copilot auto model selection on September 14, 2026 with three tiers: efficiency, balance, and intelligence. All three use the same available model set, but apply different priorities to cost, quality, and response time. This is not a new model launch. It turns the system’s per-prompt model routing into a user-adjustable objective.
Efficiency prioritizes lower cost for straightforward tasks. Balance weighs cost, quality, and latency for everyday work. Intelligence prioritizes quality for more complex tasks. GitHub’s example is that adding a docstring to existing code may use a smaller, efficient model even when Auto is optimizing for intelligence.
Auto still evaluates each prompt and selects what it considers the best-suited model. The tier is therefore not a permanent model pin; it is an optimization target for the router. For agent workflows, that can put short tasks, everyday coding, and deeper analysis behind one entry point, while making the exact model used for any call less obvious.
The feature is rolling out in Visual Studio Code, Copilot CLI, and the GitHub Copilot app. Usage is charged according to the model Auto selects regardless of tier, while paid subscribers keep a 10% discount on usage billed through Auto. Teams estimating cost should inspect the actual model mix rather than treating the tier label as a price guarantee.
For development teams, the three tiers offer a clearer cost-control surface than always using the strongest model. Efficiency may fit formatting, short explanations, and low-risk changes. Balance can cover everyday coding and review. Intelligence can be reserved for design, debugging, and cross-file work that needs more reasoning. These are workflow hypotheses that still need validation against error and acceptance rates.
Auto model selection also creates an observability requirement. If the system routes prompts to different models, teams need to know which tasks went where, how cost changed, whether latency improved, and whether quality regressed. A single aggregate usage number makes it difficult to distinguish an effective routing policy from repeated retries in one class of task.
In enterprise environments, the tier needs to sit alongside policy and permissions. An organization can define defaults by repository, team, or work type, then use spend controls, model allowlists, and audit logs to limit the available surface. Automatic model choice should not bypass data classification, code permissions, secret protection, or human approval for agent actions.
The update turns model selection from hidden infrastructure behavior into a product setting that teams can discuss and test. It does not prove that cost will fall or quality will rise, but it provides a control surface for A/B comparison. A mature rollout defines success for each task class and measures cost, latency, quality, and human intervention together rather than assuming the intelligence tier is always better.