On September 30, 2026, NVIDIA described a path from PyTorch development to production inference for an HSTU generative recommender. A generative recommender treats user interactions, context, candidate items, and actions as sequence tokens and predicts or ranks the next relevant items. That is attractive for personalization, but long histories and large embedding tables make serving expensive.
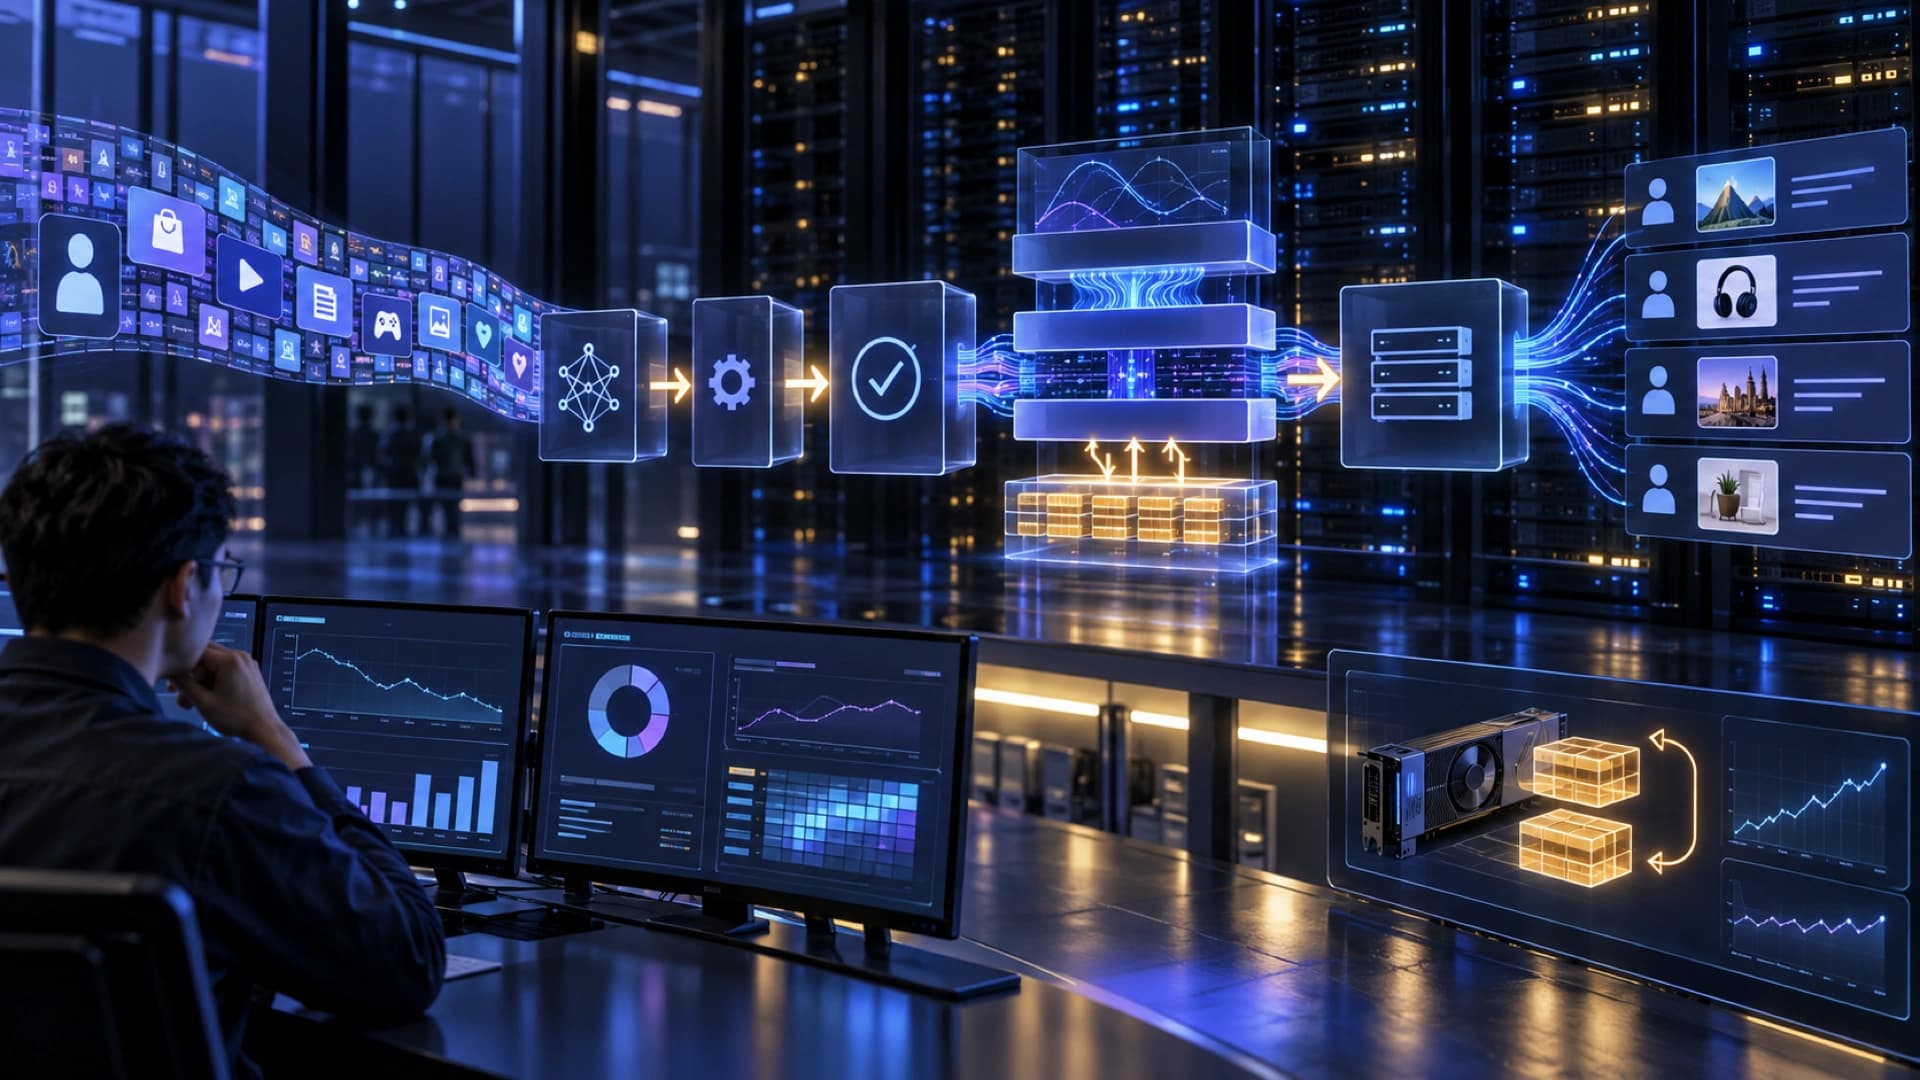
NVIDIA’s end-to-end workflow combines HSTU, PyTorch Ahead-of-Time Inductor (AOTI), FlexKV-backed KV caching, native C++ validation, NV Embedding Cache, and Dynamo-Triton. AOTI exports the model into a deployment artifact that a native C++ runtime can load. The KV cache reuses attention state already computed for a user history, avoiding recomputation of a stable prefix on every request.
In NVIDIA’s single-GPU benchmark, an RTX PRO 6000 Blackwell Workstation Edition with dynamic batch size 8 and a 100% GPU KV-cache hit rate produced a best-case speedup of 4.47x for the three-layer HSTU model and 5.93x for the eight-layer model, relative to the same AOTI configuration without caching. The post also reports 0.423 ms and 0.678 ms latency at batch size 8 for the three- and eight-layer models with cache hits. These are vendor technical benchmark results on a KuaiRand-1K ranking configuration, not a guarantee for every recommendation workload.
The deployment path separates export, compilation, the cache service, C++ replay validation, and Dynamo-Triton serving. That structure is relevant to AI marketing, feeds, advertising, and commerce because ranking latency can affect page responsiveness and ad-serving deadlines. The gain, however, depends heavily on reusable history prefixes, cache-hit rates, memory capacity, and eviction behavior. Cold starts, cache invalidation, data freshness, and different user distributions need separate measurement.
Another important detail is that development validation and production serving use the same exported artifact. Python export scripts create the package, native C++ executables replay tensors for correctness and performance checks, and Dynamo-Triton serves the result. This removes one class of runtime rewrite, but it does not solve data access, privacy, bias, exploration, or business-metric questions in a recommender system.
The NVIDIA result is a useful engineering starting point for teams moving long-sequence recommendation from model research toward serving. Benchmark interpretation should include the hardware, batch size, sequence length, cache-hit assumption, and what the measurement excludes. Before production, teams still need to retest cold and warm traffic, tail latency, recommendation quality, cost, and user experience with their own data.