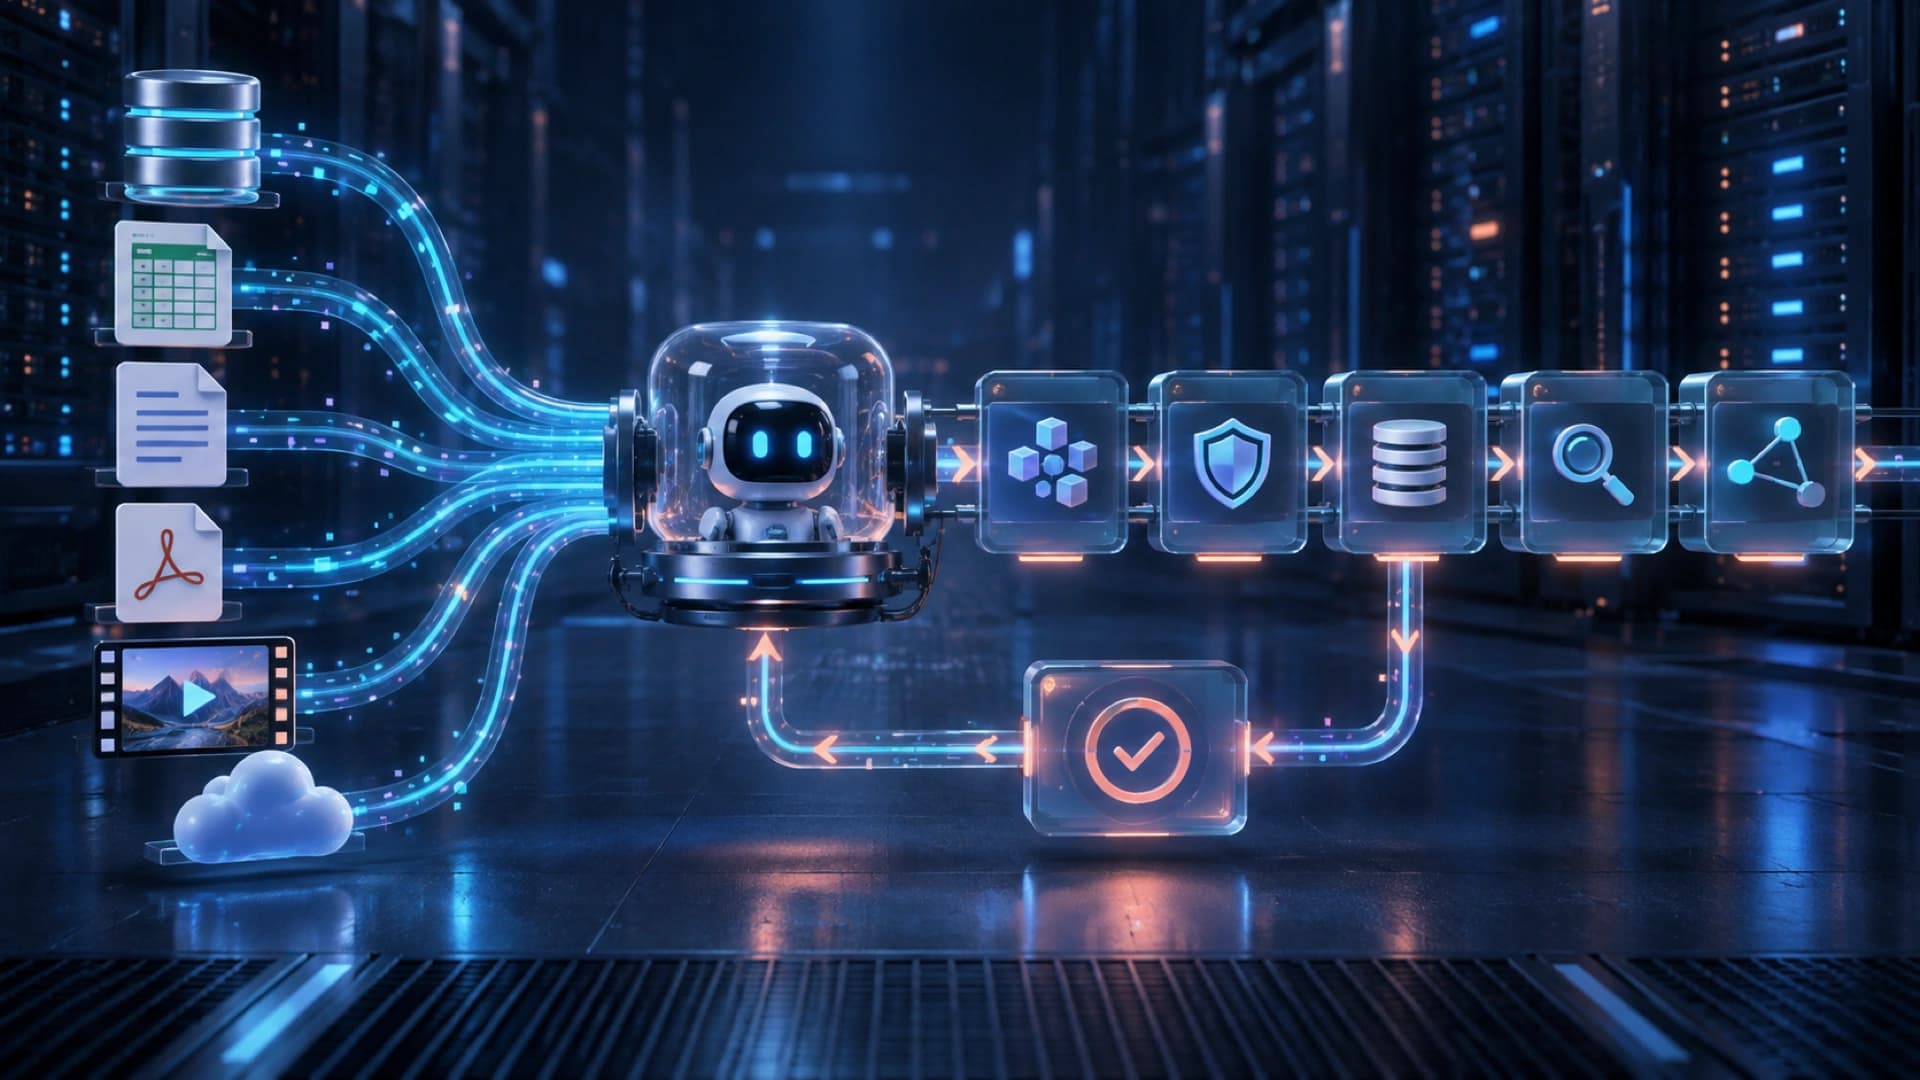
On October 8, 2026, NVIDIA described how its KGMON team placed second in the KDD Cup 2026 Data Agents competition. The competition asked agents to answer natural-language questions over heterogeneous databases, CSV and JSON files, prose documents, PDFs, and briefing videos. This was more than retrieval: the agent had to choose tools, reason across sources, produce an answer file, and handle traps in analytical workflows.
The competition used a small fixed LLM, making the harness rather than model selection the main optimization surface. KGMON followed two principles. First, it constrained the action space so the agent had fewer ways to inspect data, call tools, and recover from errors. Second, it made every attempt inspectable by preserving prompts, tool calls, SQL queries, intermediate results, errors, repairs, and final answers, allowing people and an inspector agent to find where a run first went wrong.
For structured data, the team converted CSV and JSON files into tables in an existing SQLite database, giving the agent one query surface. A custom environment exposed schema() and sql(query). Before the main reasoning loop, a schema scout summarized tables, columns, likely join keys, duplicate names, units, null patterns, and row-grain issues, reducing the number of turns spent guessing the data structure.
KGMON also narrowed the tool surface to a few helpers for schema inspection, SQL, prose lookup, and answer writing, including schema(), sql(query), write_answer(df), and prose_helper(). Middleware repaired malformed tool calls, while persistent state let the agent reuse intermediate results. Documents were handled through limited previews and targeted searches, followed by a separate zero-temperature LLM call that extracted rules or tables without loading the full source into the main agent context.
When a task included a briefing video, the system first extracted keyframes, transcribed audio, and aligned transcript segments with frames so the agent received organized evidence. These preprocessing and tool choices were shaped by the competition and are not a universal production recipe. NVIDIA notes that the solution was influenced by a fixed model, no internet access, heterogeneous task bundles, value-level scoring, and a long-run budget.
The more portable lessons are to normalize data access, give the agent a small and reliable tool surface, log complete execution traces, and evaluate both answers and trajectories. Improvements should use held-out tasks rather than hard-coding benchmark examples into prompts. People still need to define success criteria, audit traces, reject brittle fixes, and promote harness changes only after cost, risk, and generalization are acceptable.